The Metric Role Map: one system, five layers
Ask three executives which performance-management system the company should run and you will usually get three confident answers: OKRs, KPIs, or the North Star metric. The question itself is the problem. These are not rival philosophies competing to run your company; they are instruments built for different jobs. The OKR Institute puts it plainly: KPIs and OKRs are not competitors but complementary tools, a business health dashboard on one side and a strategic transformation engine on the other, and organizations that try to replace one with the other typically fail to execute on both[1]. John Doerr's team frames the same split in one sentence: a KPI tells you how you are doing, while an OKR tells you where you are trying to get[2]. Choosing between them is a category error, like choosing between a compass and a speedometer.
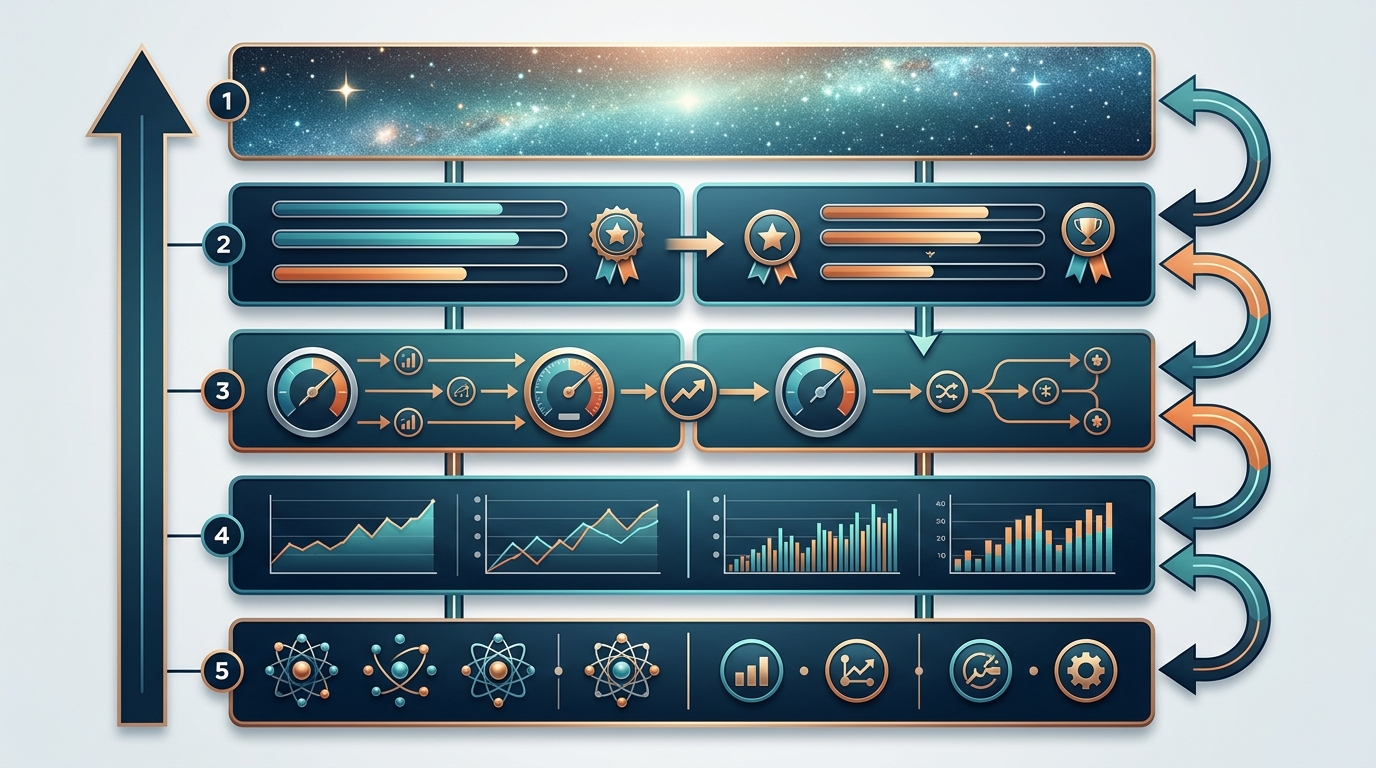
The useful move is to stop choosing and start assigning roles. THE METRIC ROLE MAP is a five-layer architecture that gives every metric in the company exactly one job. It looks like this:
| Layer | System | Question it answers | Review rhythm |
|---|---|---|---|
| DIRECTION | North Star metric | What does winning look like? | Annual, or when strategy shifts |
| OUTCOME | OKRs | Which ambitious shifts do we commit to this quarter or year? | Weekly check-ins, quarterly grading and retrospective |
| DRIVER | KPIs | Is the machine healthy? | Continuous dashboard, weekly or monthly operational review |
| OPERATIONAL SIGNAL | Daily and weekly telemetry | What changed since yesterday? | Live feeds, watched as they move |
| REVIEW CADENCE | Governance layer | Who inspects which layer, and when? | A fixed calendar that covers all four layers above |
Framework debates miss the real failure because the failure is rarely the label. Across more than 21,000 strategic plans, ClearPoint found that only about 27% of KPIs and just 10% of objectives are ever actively scored, and 76.4% of the people assigned to own a metric have never recorded a single update against it. Switching from KPIs to OKRs, they conclude, does not fix neglect; it just gives neglect a more ambitious name[3]. Execution and ownership break the system, not vocabulary.
That is why the diagnostic question for any metric is not "should we use OKRs or KPIs" but "which layer does this metric belong to?" A number that captures the value you deliver is DIRECTION. A commitment to move a number well beyond its baseline this quarter is OUTCOME. A gauge you watch continuously to know the machine is healthy is DRIVER. The telemetry underneath is OPERATIONAL SIGNAL. And the discipline that decides who looks at each layer, how often, is REVIEW CADENCE. The rest of this article walks the map layer by layer.
DIRECTION: what a real North Star metric is
The DIRECTION layer holds one number: the metric that best captures the intrinsic value the company creates for customers. Amplitude, which popularized the North Star Framework, defines it as the single metric that best captures the value customers derive from your product, and insists it do three things at once[4]. Those three things are the quality tests any candidate must pass:
- It represents real customer value: the metric measures the moment the customer actually gets the "aha", not the moment your systems register activity.
- It sits within the team's sphere of influence: the people asked to move it can plausibly move it through product, marketing, and service decisions.
- It is a leading indicator of revenue: it predicts future revenue rather than recording past revenue, because the further upstream of revenue you get, the more future impact you can drive.
The test exposes why lagging financials make bad North Stars. ARR, MRR, registered users, daily active users, and page views either record what already happened or say nothing about what customers value. Amplitude is explicit that DAU and registered users fail the customer-value test[4]. The widely cited good examples share a shape: Airbnb's nights booked, Spotify's time spent listening, Slack's messages sent within an organization. Each names the exchange of value as it happens, is hard to game with vanity activity, and is simple enough to be understood at every level of the company, from the board to the newest hire[5].
Beneath the North Star sits an input-metric tree: three to five levers that teams can actually move and that collectively produce the North Star, often organized around breadth, depth, frequency, and efficiency of engagement[4]. This tree matters because it is the connective tissue to the layers above and below: OKRs will pick which inputs to move this quarter, and KPIs will watch them continuously.
Be clear about what the North Star does not provide, because that is where naive implementations collapse. It offers no quarterly planning cycle, no named ownership per metric, no weekly accountability mechanism, and no cascade from company to team. It identifies what matters; it does not build the execution infrastructure for moving it. A North Star alone is a poster, not a system[5].
OUTCOME: what OKRs are good at
The OUTCOME layer is where commitment happens. An OKR pairs one ambitious, qualitative Objective with two to four measurable Key Results, and its purpose is fundamentally different from monitoring: OKRs exist to force change rather than watch the steady state. The OKR Institute's comparison is precise on this. KPIs are realistic and attainable, with 100% achievement expected; OKRs are ambitious, where 60 to 70 percent achievement counts as strong progress. KPIs run continuously; OKRs reset each quarterly cycle. KPIs are typically set top-down; OKRs are meant to be co-created bottom-up by the teams doing the work[1].
- A real Key Result has a baseline, a target, and a date: reduce churn from 4.2% to 2.8% by the end of Q3, not maintain churn below 4%.
- It describes a change in the business, not an activity: launch, conduct, track, and complete are task verbs, not outcome verbs.
- There are only two to four of them per Objective, because an Objective with ten Key Results is a project plan wearing a strategy's clothes.
The 60 to 70 percent expectation is not softness; it is the design. OKRs are stretch commitments, set beyond what the current machine would deliver anyway. The elevation move is the practical heart of the layer: when a KPI drifts red and no amount of steady-state management fixes it, the organization commits to moving it well beyond baseline, and that drifting KPI becomes a Key Result. What Matters' racing-team example shows the shape: the team's business as usual is driving excellence, but winning the Indy 500 requires a significant improvement in pit-stop times, so reducing pit-stop times becomes the Objective, framed as a result rather than a task like conducting an analysis or hiring a new pit leader[2]. Doerr calls OKRs "KPIs with soul" for exactly this reason: same numbers, added direction and purpose.
One structural rule separates serious OKR programs from performative ones: the OKR layer stays deliberately separate from compensation, while KPIs can reasonably connect to operational delivery thresholds. The OKR Institute's reasoning is direct. Tying OKRs to bonuses creates sandbagging, where teams set easy objectives to guarantee full achievement instead of ambitious ones; KPIs, which measure consistent operational delivery, can carry that weight without breaking[1].
Where OKRs fail: checklists, gaming and drift
The OUTCOME layer fails in predictable, well-documented ways, and the benchmark data is specific enough to diagnose each one. OKRs Tool's research across hundreds of organizations and tens of thousands of Key Results found four structural failure modes that account for most of the damage[6]:
| Failure mode | What it looks like | Benchmark signal |
|---|---|---|
| Proliferation | Teams carry three or more OKRs per quarter and never retire old ones | Teams running one or two OKRs a quarter are twice as likely to hit them as teams running three or more |
| Tasks in disguise | Key Results written as activity: launch, complete, conduct, track | 52% of 7,857 analyzed Key Results were tasks or KPIs in disguise, measuring activity rather than change |
| Missing ownership and cascade drag | Shared or vague accountability; alignment arrives weeks into the quarter | 50% of Key Results have no named single owner; only 16% of organizations complete the full cascade within the first week |
| Gamed grading | Scores become performative; goals are set to be achieved, not to change anything | 92% of employees admit at least one form of goal-gaming; 96% sandbag when goals directly affect performance ratings |
Proliferation deserves a closer look because it compounds quietly. A team starts with two Objectives, keeps last quarter's half-finished ones alive, absorbs a corporate initiative, and by the third cycle is running six goals nobody can name. Accumulation without retirement kills focus within three cycles, and the data confirms the cost: objectives with one or two Key Results outperform those carrying four or more, and teams that skip end-of-cycle retrospectives never prune, because nothing forces the question of what to stop[6].
Gaming is the failure mode leaders underestimate most. In the State of Goal Management survey, 89% of employees admitted setting a goal they had already mostly achieved, 70% admitted reporting a goal healthier than they knew it to be, and 43% admitted all three behaviors in the same cycle. The single strongest driver is consequence design: 96% sandbag when goals directly affect performance ratings, versus 81% when goals are kept separate. The grading ritual itself becomes the product, and the numbers stop describing the business[6].
DRIVER: what KPIs are for, and where they fail
The DRIVER layer monitors the machine. KPIs watch steady-state health: churn, response time, uptime, attrition, conversion. They have no start date and no finish line; they are tracked every week, indefinitely, and their job is to tell you when something healthy turns sick. The test from OKRs Tool is clean: if you could track the metric every week forever without it ever being complete, it is a KPI and belongs on the dashboard, informing the OKR planning process rather than living inside it[7].
Most companies have exactly the inverse of the right ratio: too many KPIs and too few OKRs. ClearPoint's dataset of 21,000+ strategic plans shows the average plan carries about five measures for every objective, yet only 27% of KPIs are actively scored and only 10% of objectives are evaluated at all. Worst of all, 76.4% of metric owners have never recorded a single update against the metric they nominally own[3]. The risk was never too few numbers; it is too many numbers, watched by too few people.
Why does the pile grow? Because KPIs get chosen because they are measurable rather than because they matter. Any system the company already logs can be counted, so the dashboard accretes whatever is easy to extract, and the plan becomes a binder. The state health agency at the extreme of ClearPoint's data tracked more than 33,000 measures and actively scored 372 of them; nobody chose that outcome, the metrics simply piled up a program at a time[3].
- A metric is a gauge: it describes the current state of the machine and carries no commitment.
- A target is a commitment layered on top of a metric: a specific value to be reached by a specific date, with a name attached.
- Confusing the two produces dashboards full of gauges nobody is committed to moving, and targets with no gauge underneath to tell you whether the machine can sustain the change.
The lean-plan data closes the loop on where KPI discipline pays. Plans keeping under three measures per objective actively score 49% of them, versus 16% for plans carrying twelve or more. You do not need more discipline; you need a shorter list[8].
How the three layers fit together: cascade and cadence
Run as one system, the layers divide the work cleanly. The North Star sets direction: the single number that defines winning. OKRs choose this quarter's bets: which input metrics each team will move, by how much, with a named owner on every Key Result. KPIs monitor the machine in between: the continuous gauges that tell you whether the business stays healthy while the change work happens. OKRs Tool's architecture statement is the cleanest formulation of the dependency: a North Star without OKRs becomes a number everyone agrees is important and nobody is specifically accountable for moving, while OKRs without a North Star become well-executed quarterly work that does not compound toward anything transformational[5].
The cascade is where the system lives or dies, and it must not be mechanical. Translating every company objective into copied team objectives produces alignment theater: 65% of organizations set OKRs primarily top-down, and 65% of teams admit their goals are not clearly linked to company strategy anyway. The behavioral data shows why co-creation wins: in top-down structures, a missed OKR most often triggers a formal accountability conversation, while in collaborative structures it is analyzed in the retrospective and fed into the next cycle. Same miss, opposite learning[9]. Team OKRs should reference the company direction and be written by the teams who will deliver them, not distributed to them.
- DRIVER and OPERATIONAL SIGNAL: continuous dashboards, with weekly or monthly operational reviews to catch anything drifting out of range.
- OUTCOME: weekly check-ins of 15 to 20 minutes on progress, blockers, and decisions, plus quarterly grading and a retrospective; teams with the weekly habit complete 43% more OKRs than those reviewing monthly or ad hoc.
- DIRECTION: an annual review, or an explicit re-examination whenever strategy shifts, because a North Star that changes quarterly was never a direction.
The closing loop is the quarterly retrospective, and its key question is upward: did this quarter's Key Results actually move the North Star? If the OKRs were achieved but the North Star did not budge, the input-metric tree was wrong, not the teams. That question is what turns three separate systems into one compounding one, and it is the same bridge between strategy and execution that an ongoing management system, rather than an annual planning event, exists to provide Strategy Execution System[10].
Failure modes and running the map from the CEO office
Three failure modes cut across every layer of the map, and all three are incentive problems rather than framework problems. The first is Goodhart's law: when a measure becomes a target, it ceases to be a good measure. Push any metric hard enough and people optimize the metric instead of the mission; hospitals discharge early to shrink length-of-stay, schools teach to the test. Its quieter cousin is surrogation: people start serving the proxy instead of the strategy, and the number stops representing the thing it was chosen to stand for. Research documented by ClearPoint shows surrogation sets in even without a bonus attached[3].
The second is the ratchet effect. Tie goals to pay and you invite sandbagging: the benchmark finding that 96% of employees set goals they had already mostly achieved when those goals affect performance ratings is the ratchet in action, and it is why the OUTCOME layer stays separate from compensation while the DRIVER layer, which measures consistent operational delivery, can carry threshold-based consequences[6]. The third is metric proliferation, already visible in the five-measures-per-objective average and the 33,000-measure plan: every layer drifts toward accumulation unless someone actively retires metrics.
Running the Metric Role Map is therefore a governance job, and it sits naturally with the CEO or CSO office. The work is concrete: classify every existing metric into its layer, force one North Star and its three-to-five inputs onto a single page, hold the OKR count at one or two Objectives per team, name an owner for every Key Result, and publish the review calendar so no layer is inspected only when a meeting demands it. This is where an AI-native strategy platform such as Decisity earns its place: used from the CEO office, it structures the layers directly on the company's own performance documents, keeps ownership explicit, and keeps every figure on a board deck traceable to its underlying source, which is exactly the evidence discipline boards now expect from C-level reporting C-level & Boards.
The platform's working model fits the map layer by layer: documents and scoping go in, specialist agents structure the problem and cross-reference the sources, and board-ready deliverables come out with every claim clickable to its evidence How it works. For the DIRECTION and OUTCOME layers specifically, the underlying strategy engine applies MECE structuring and the pyramid principle to keep the metric tree and the quarterly bets internally consistent rather than a collection of slides AI Strategy Engine.
The final word belongs to the diagnostic, not the vendor. When the next framework debate starts, skip the labels and run the map instead: one number for DIRECTION, a handful of committed shifts for OUTCOME, a short list of gauges for DRIVER, telemetry underneath, and a calendar that inspects each layer at its own rhythm. Companies rarely fail from choosing the wrong framework. They fail from giving every metric the same job, and then never looking at any of them honestly.
Related: Decisity for C-level and boards.