Why AI capital allocation is now a CFO problem
Enterprise AI spend has outgrown the IT budget conversation. It now behaves like a portfolio of capital bets: dozens of pilots, a handful of production systems, and a stream of funding requests that all arrive wrapped in the same optimistic language. The evidence says most of that capital is not working. MIT's NANDA initiative, in its report The GenAI Divide: State of AI in Business 2025, found that about 95% of enterprise generative AI pilots deliver little to no measurable impact on the P&L, with only around 5% achieving rapid revenue acceleration[1].
Read as a technology story, those numbers suggest the models do not work. Read as a finance story, they say something more actionable: the capital process around AI is undisciplined. Initiatives are funded on enthusiasm, reviewed against no fixed yardstick, and abandoned late, after the money is spent, rather than on a schedule. That is a spend-governance failure, and it sits squarely in the CFO office's remit.
- AI spend is now large enough and diffuse enough that nobody can govern it by walking around; it needs the same portfolio view portfolio management applies to any other set of capital bets.
- Pilot failure is usually an allocation failure, not a model failure: the wrong use case was funded, against the wrong yardstick, for too long.
- The CFO office already owns the discipline for every other category of investment; AI earns no exemption from it.
One boundary matters. Board-level oversight of AI risk, including the questions directors should ask management and the governance frameworks they should demand, is a distinct discipline that we cover separately in our articles on AI governance for boards. This article stays below the boardroom: it is about the operating cadence the CFO office and FP&A run to decide, initiative by initiative, what gets more money, what stays flat, and what gets killed.
Who owns the AI budget: business unit, central IT or shared services
Before any cadence can work, someone has to own the money. In practice enterprises settle into one of three ownership models, and each fails in a predictable way.
| Ownership model | Strength | Characteristic failure |
|---|---|---|
| Business unit owns AI spend | Closest to the P&L; value owners cannot hide from outcomes | Fragmentation: duplicated tools, no platform leverage, shadow subscriptions |
The data suggests most organizations have not chosen at all. Deloitte observes that AI spending is now spread across teams and departments, from usage-based costs to R&D-style experimentation, which creates the need for AI-specific profit-and-loss views to get a true sense of ROI[2]. Bain finds that governance accountability for AI is currently split almost evenly between IT, business functions and central teams, with no clear owner in most organizations[3]. When everyone owns the budget, no one owns the allocation decision.
The workable split assigns three different things to three different owners:
- Business units own value delivery. The P&L owner of the process an AI initiative touches is accountable for the outcome, not for the technology.
- A central team owns the platform and enablers: model access, security, integration standards, vendor management and shared tooling.
- The CFO office owns the portfolio view and the allocation decision. It does not run projects; it decides, on evidence, which ones get the next dollar.
Where the money goes: the anatomy of AI spend
AI budgets look opaque because they are usually reported as one line. In reality the spend decomposes into four buckets with completely different cost behavior, and the differences drive how each should be governed.
| Cost bucket | What it covers | Cost behavior |
|---|---|---|
| Model and API token costs | Metered usage of foundation models, per prompt and per output | Usage-based and volatile; scales with adoption, not with headcount |
The critical distinction is between a pilot budget and a production budget. A pilot proves feasibility on a small slice of usage. Production requires the security review, monitoring, ownership, integration and change management that the pilot never carried, and that layer is usually unbudgeted, which is a large part of why pilots stall at exactly the moment they are asked to scale. Deloitte describes the volatility problem concretely: in one large healthcare enterprise, token usage growth of 8% to 10% per month translated into more than $6 million in annualized, previously unplanned cost increases before the finance team had visibility into the driver[4].
The governance consequence follows directly: because model costs are usage-based, spend scales with adoption. A decision to scale an initiative is therefore simultaneously a cost decision. The CFO office cannot approve scale and discover the bill later; the unit economics at production volume belong in the same decision.
The AI Capital Discipline Loop: from use case to decision
To make those decisions repeatable, the CFO office needs a loop it runs on every initiative, every cycle. We call it THE AI CAPITAL DISCIPLINE LOOP. It has six steps:
- Use case. A named business process, owned by a named business owner, with the intended users identified before funding. Not a technology in search of a problem.
- Spend. The fully loaded cost across all four buckets, including the production layer, with the usage-based portion modeled at the relevant volume.
- Adoption. Whether the intended users actually use the tool, at what frequency and depth, measured against a threshold set at funding time.
- Evidence. The documented link between usage and a financial mechanism: which line of the P&L moves, through what pathway, verified against the company's own numbers.
- Business value. The measured impact on that mechanism, net of the full cost, stated in the same terms as any other capital investment.
- Scale, hold or kill decision. The explicit allocation call: more capital, flat funding while evidence matures, or stop and reallocate.
Adoption evidence is not value evidence
The step most organizations skip is the distinction between the two kinds of evidence. Adoption evidence answers: are the intended users actually using it, how often, and how deeply in their workflow? A tool with high login counts and shallow usage is a toy. Value evidence answers a harder question: is there a documented financial mechanism, a named pathway from usage to cost reduction or revenue, with a measurable P&L impact? MIT Sloan Management Review's research finds that few companies apply the same financial discipline to AI as they would to a new factory or piece of machinery, and that two companies making nearly identical investments may define success in entirely different ways[5]. The loop exists to close that gap: every initiative is judged on the same six steps, with the same evidence standard, every cycle.
Scale criteria: what earns the next dollar
Scaling is a capital decision, and it should be gated on three criteria, all three met, not two out of three:
- A financial mechanism is identified. Not a generic productivity hope, but a named pathway from usage to a specific cost line or revenue line, sized against the company's own baseline.
- Adoption is above a pre-set threshold. Frequency and depth of use by the intended user group, measured against the threshold that was set when the initiative was funded, not invented afterward.
- A business owner is accountable. Someone in the business unit who owns the process and the outcome, not a project champion whose day job ends when the pilot report is written.
Hold is a legitimate outcome, and treating it as one protects the portfolio from both errors. Flat funding while evidence matures is the right call for an initiative with a credible mechanism but thin adoption data, or strong adoption but an unfinished value case. What hold is not is a parking lot: an initiative on hold carries a named condition and a date, and returns to the loop like everything else.
Build-versus-buy belongs in the scale decision too. MIT's research, as reported by Fortune, found that purchased solutions reach production about 67% of the time, while internal builds succeed roughly a third as often[1]. The practical implication for the CFO office is a higher evidence bar for scaling an internal build: the same capital committed to a bought-and-integrated solution should be expected to clear the three criteria faster, so an internal build must show stronger adoption and a more concrete mechanism before it earns the next dollar.
Kill criteria: why killing is the hardest AI decision
Killing an AI initiative is harder than killing any other kind of project, because the people who decide are usually the people who sponsored it, and the technology narrative makes every stall sound like a timing problem rather than a verdict. That is exactly why the kill criteria have to be set before the money moves. Three triggers justify a kill:
- No meaningful adoption after a set number of months, for example two review cycles, against the threshold set at funding time.
- No identifiable financial mechanism: after repeated cycles, nobody can name the pathway from usage to a P&L line.
- Opportunity cost of talent: scarce AI-capable engineers, analysts and product people locked into a dead initiative are the most expensive hidden cost in the portfolio.
Sunk cost is the enemy of AI capital discipline. The money already spent is gone regardless of what happens next; the only question the loop is allowed to ask is the best use of the next dollar. Every month a doomed pilot keeps its team, it is also spending the alternative future those people could have built on a surviving initiative. CIO.com's analysis of disciplined allocators makes the mechanism concrete: attach a kill line to every initiative at the moment it is funded, a named milestone, a date and an owner empowered to stop it, and if the bet misses its milestone, it is liquidated and the capital is reallocated on schedule, without a debate over sunk costs[6].
The alternative is what the market is actually doing. Bain's survey of 951 global companies found that while 37% targeted cost reductions of 11% to 20%, nearly 40% of those that measured outcomes landed in the 0% to 10% bucket instead, and 90% of the same companies are increasing their AI budgets again anyway[3]. Funding the next wave without killing the failures that caused the last shortfall is not optimism; it is compounding the original allocation error.
The review cadence: monthly portfolio, quarterly C-suite
Criteria without a cadence decay into shelf documents. The loop runs on two clocks.
- Monthly portfolio review, run by the CFO office and FP&A. Per initiative: adoption against threshold, burn against milestone, kill-line status. Output: flag what is drifting, prepare decisions, reallocate small amounts.
- Quarterly C-suite allocation review. Scale, hold and kill decisions on the survivors, and rebalancing of capital across the portfolio. Output: the actual allocation changes, recorded with their rationale.
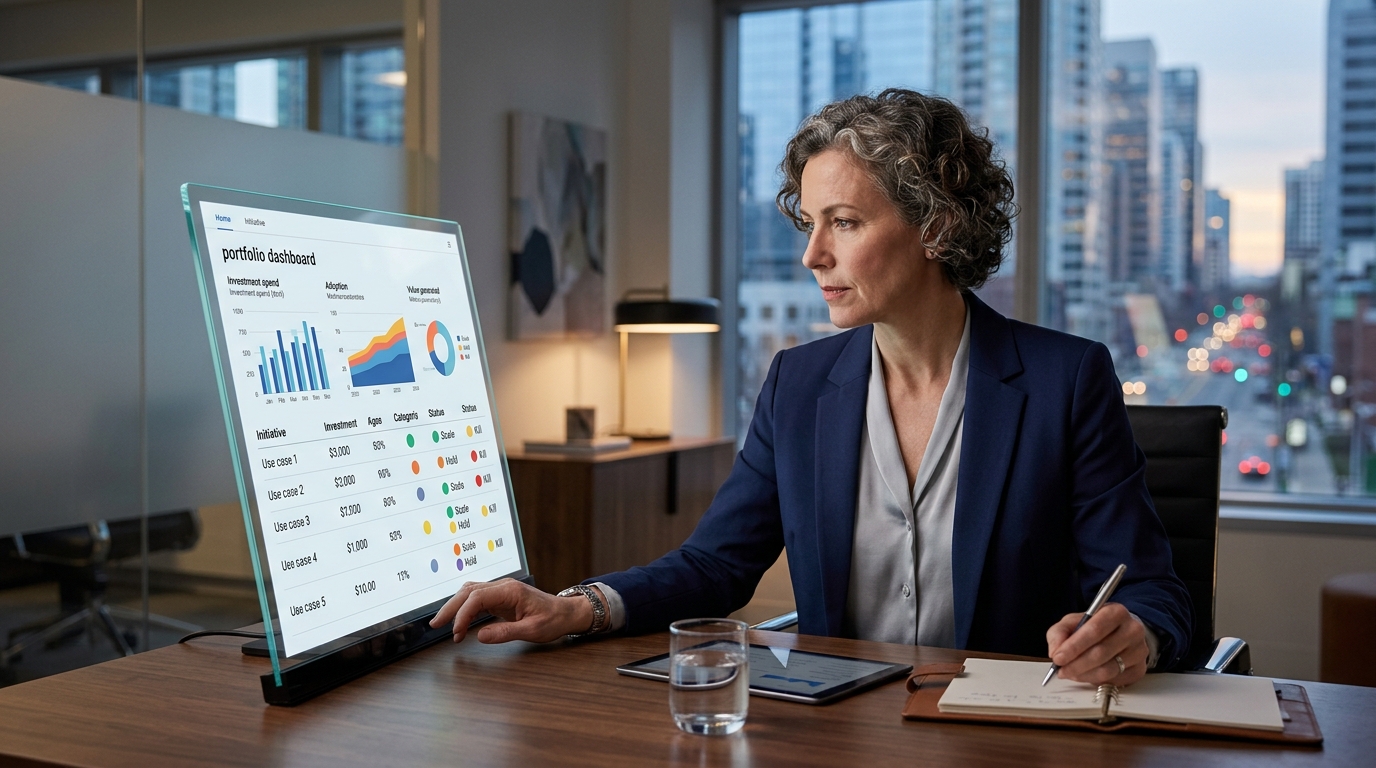
Both tiers run on a single portfolio scorecard, so the conversation is about decisions rather than status theater:
| Scorecard element | What it shows | Which tier consumes it |
|---|---|---|
| Allocation by bucket | Capital split across the four spend buckets and across scale/hold/kill states | Quarterly C-suite review |
Running this loop well is a documentation and traceability problem as much as a discipline problem: every adoption figure, cost line and value claim on the scorecard has to be traceable back to the company's own documents, or the quarterly review turns into a negotiation. This is where the CFO office puts an AI-native strategy platform to work. Decisity is used by CFO offices to structure the AI initiative portfolio on the company's own documents: the platform reads and cross-references internal material to build the portfolio view, keeps every claim on the scorecard traceable to its source, and produces the board-ready allocation decks the quarterly review runs on. The same traceability carries upward: when the allocation decisions reach the boardroom, they land in the format directors expect, with every figure clickable back to its evidence, which is exactly what the C-level and boards solution is built for. The underlying method, from document ingestion through structured analysis to a defensible deliverable, is described in how Decisity works, and the AI Strategy Engine is what enforces the source traceability behind each scale, hold or kill recommendation.
The discipline, in the end, is not the software. It is the willingness to run the loop every month, apply the same three scale criteria and the same three kill triggers to every initiative including the popular ones, and treat a kill executed on schedule as the portfolio working, not failing. The organizations that extract returns from AI are not the ones that picked better pilots. They are the ones that decided, deliberately and repeatedly, where the next dollar goes.
Related: Decisity for C-level and boards.